Twitter Spam Violation Workbench
I designed the moderator workbench to bring investigation, evidence, and annotation into one focused experience.
Improvement in SAR after 3 months in production, exceeding Twitter’s 10% target.
- Role
- Senior Product Designer, sole designer
- Client
- Innodata for Twitter
- Collaborators
- Twitter stakeholders, moderators, Innodata delivery team
- Scope
- New annotation workbench, designed from the ground up
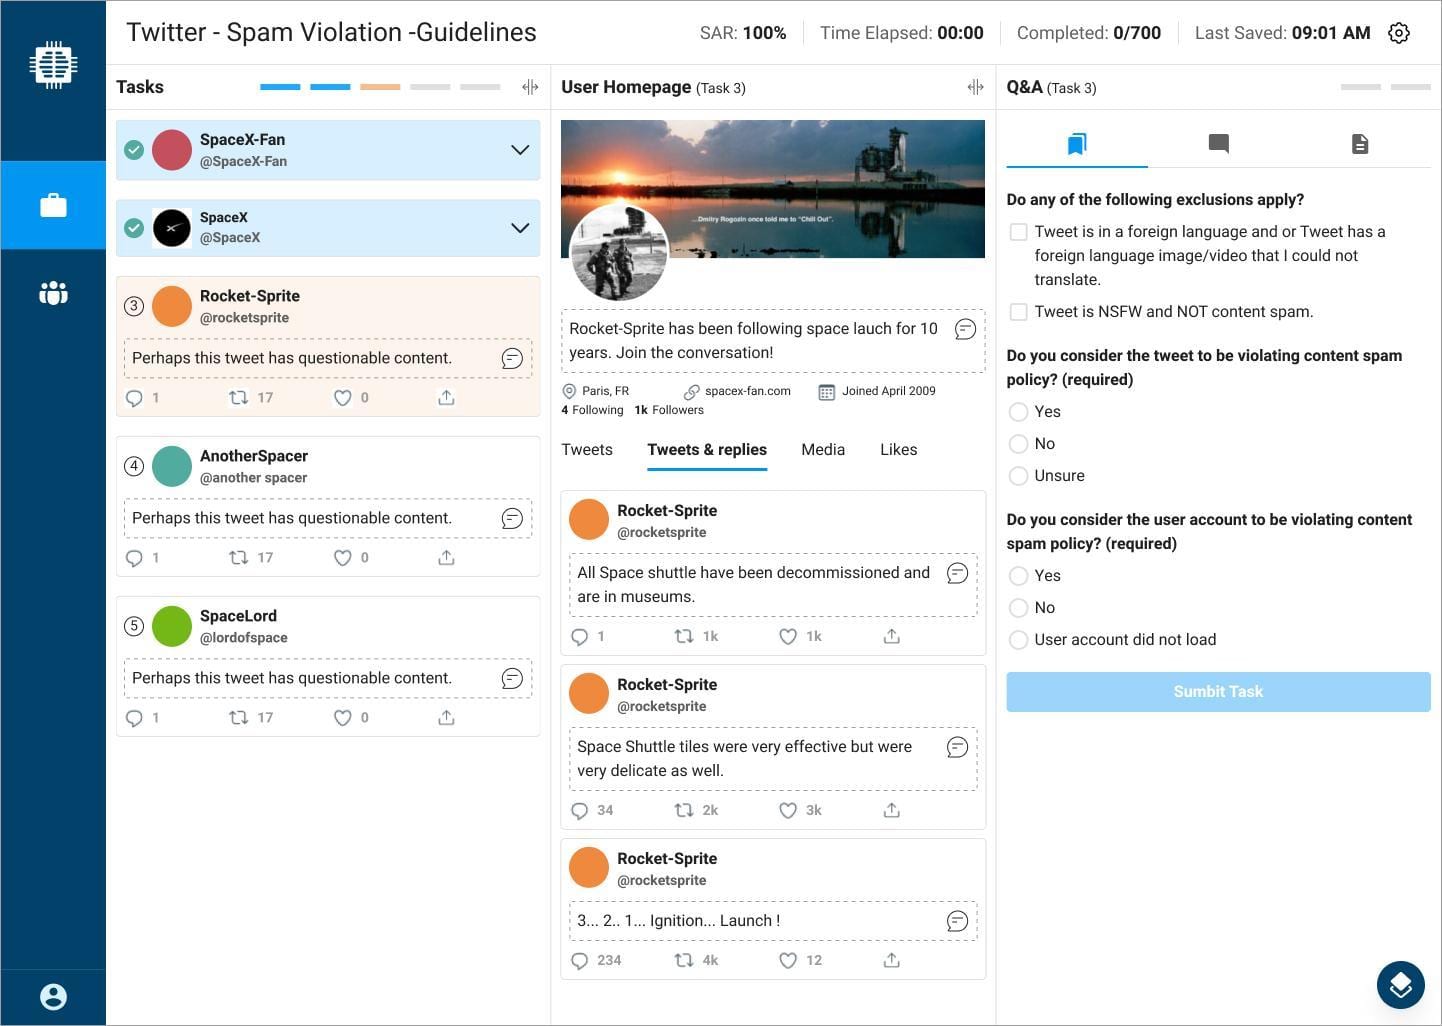
Accurate human annotations were critical to Twitter’s spam detection
Human moderators reviewed flagged tweets and classified violations, producing the annotations Twitter used to improve its spam detection models.
End-to-end UX
Research, exploration, interaction design and validation.
New annotation workbench
Designed from the ground up for high-volume moderation work.
Innodata partnered with Twitter to improve the quality of human annotations used to train its spam detection models. As the sole product designer, I owned the end-to-end UX of a new moderation workbench, collaborating with Twitter stakeholders, moderators, and Innodata’s delivery team to bring investigation and classification into one experience.
Fragmented investigation workflow
Moderators had to switch between spreadsheets, Twitter profiles, and questionnaires to investigate and classify tweets, repeatedly interrupting their work.
Too much effort between decisions
Every annotation required navigating separate tools to gather evidence and answer questions, adding unnecessary steps to an already demanding workflow.
Improve annotation accuracy by 10%
Create a focused workbench that brings investigation and annotation together.
I documented the rules and studied how moderators worked
I reviewed Twitter’s requirements to capture the annotation rules, then studied real moderator sessions to understand how those rules played out in practice.
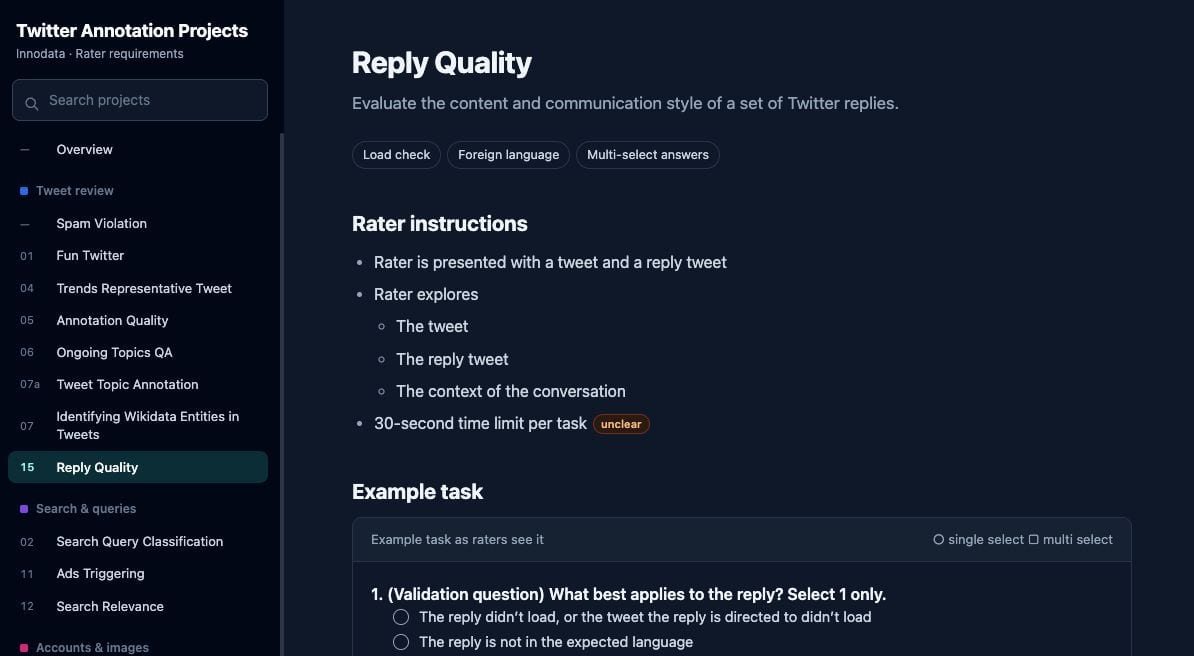
I reviewed recordings of real moderation sessions to understand how annotators moved between tasks, Twitter profiles, translation tools, and classification questions. I focused on repeated actions, unnecessary context switching, and the effort required to gather evidence before making a decision. These observations exposed workflow friction that wasn’t apparent from the annotation requirements alone.
I mapped the workflow, then challenged it with stakeholders
I refined the workflow through stakeholder reviews, a collaborative What If workshop, and technical constraints.
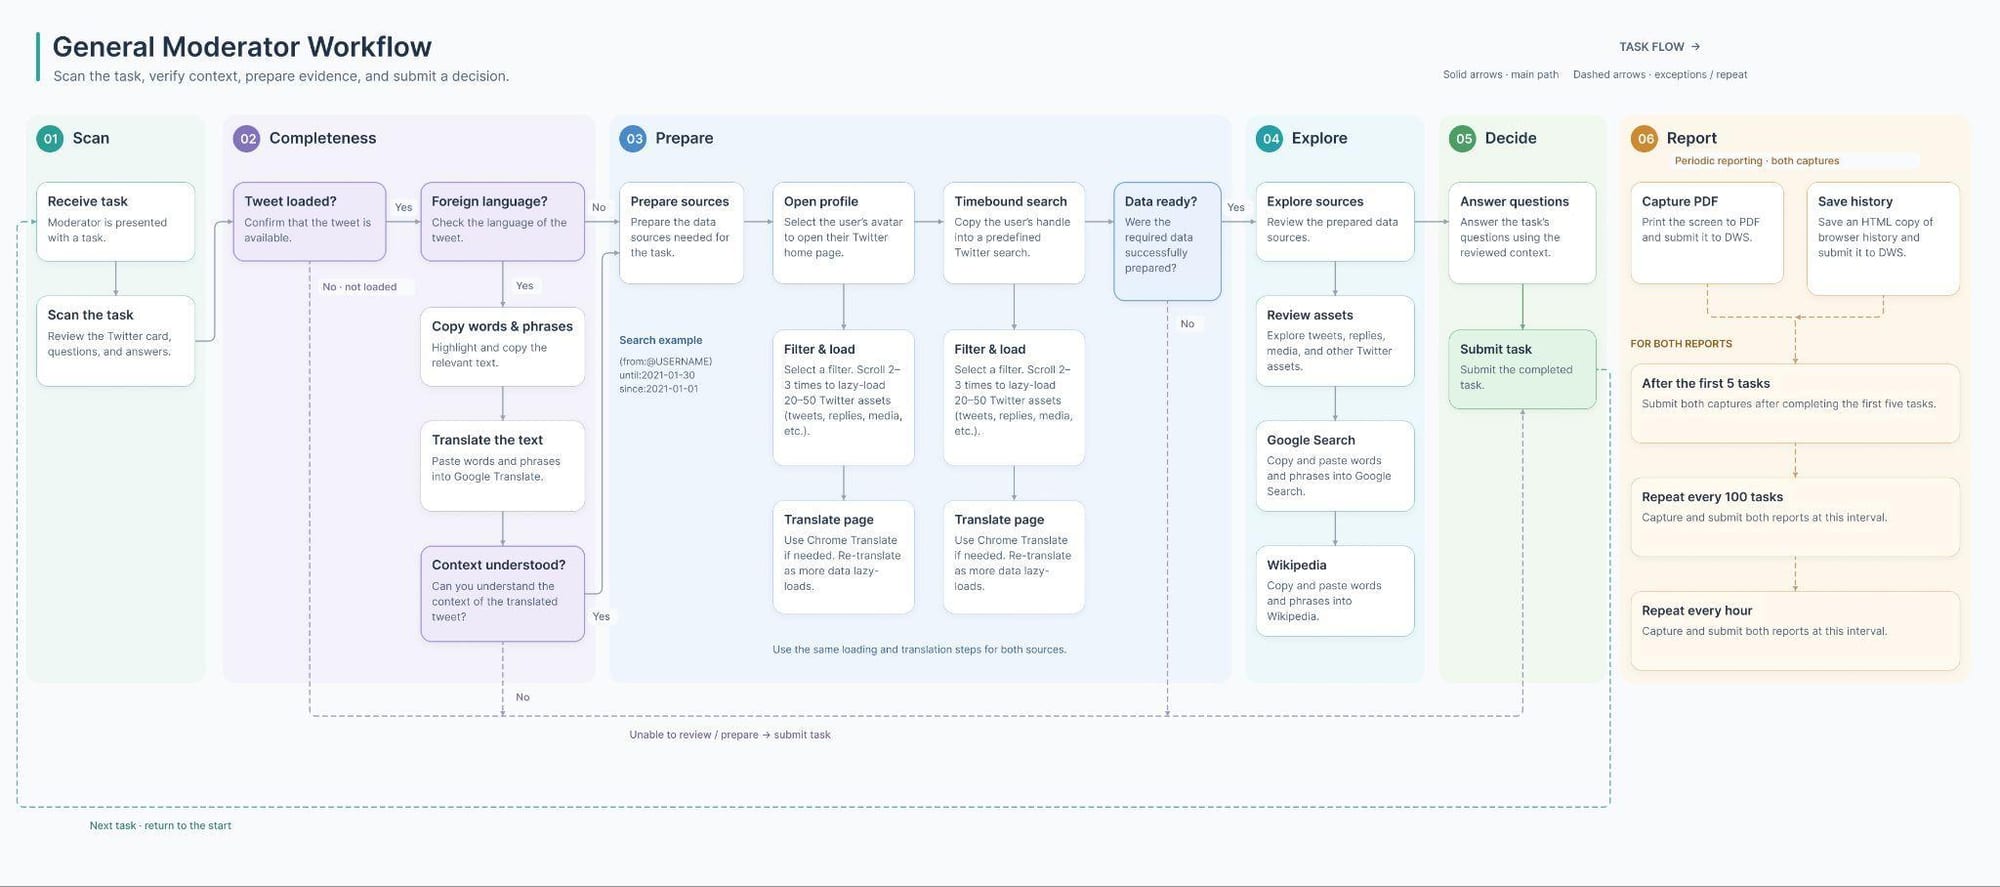
I mapped the end-to-end moderation workflow and used it to challenge assumptions with Twitter stakeholders and Innodata’s delivery team. Our discussions helped distinguish steps required for accurate classification from unnecessary navigation and repeated manual work. The resulting workflow became the foundation for a more focused workbench, balancing moderator needs with the project’s technical constraints.
Research revealed the hidden costs of manual moderation
My screencast analysis revealed repeated interruptions in a high-volume annotation process.
Context was scattered
Tasks, Twitter context and questionnaires lived in different places.
Too many manual steps
Copying, pasting and translation interrupted the investigation flow.
Repeated exposure to harmful content
Moderators routinely encountered offensive or disturbing material while investigating flagged accounts.
Testing my own assumptions against how moderators really worked
I initially optimized for convenience
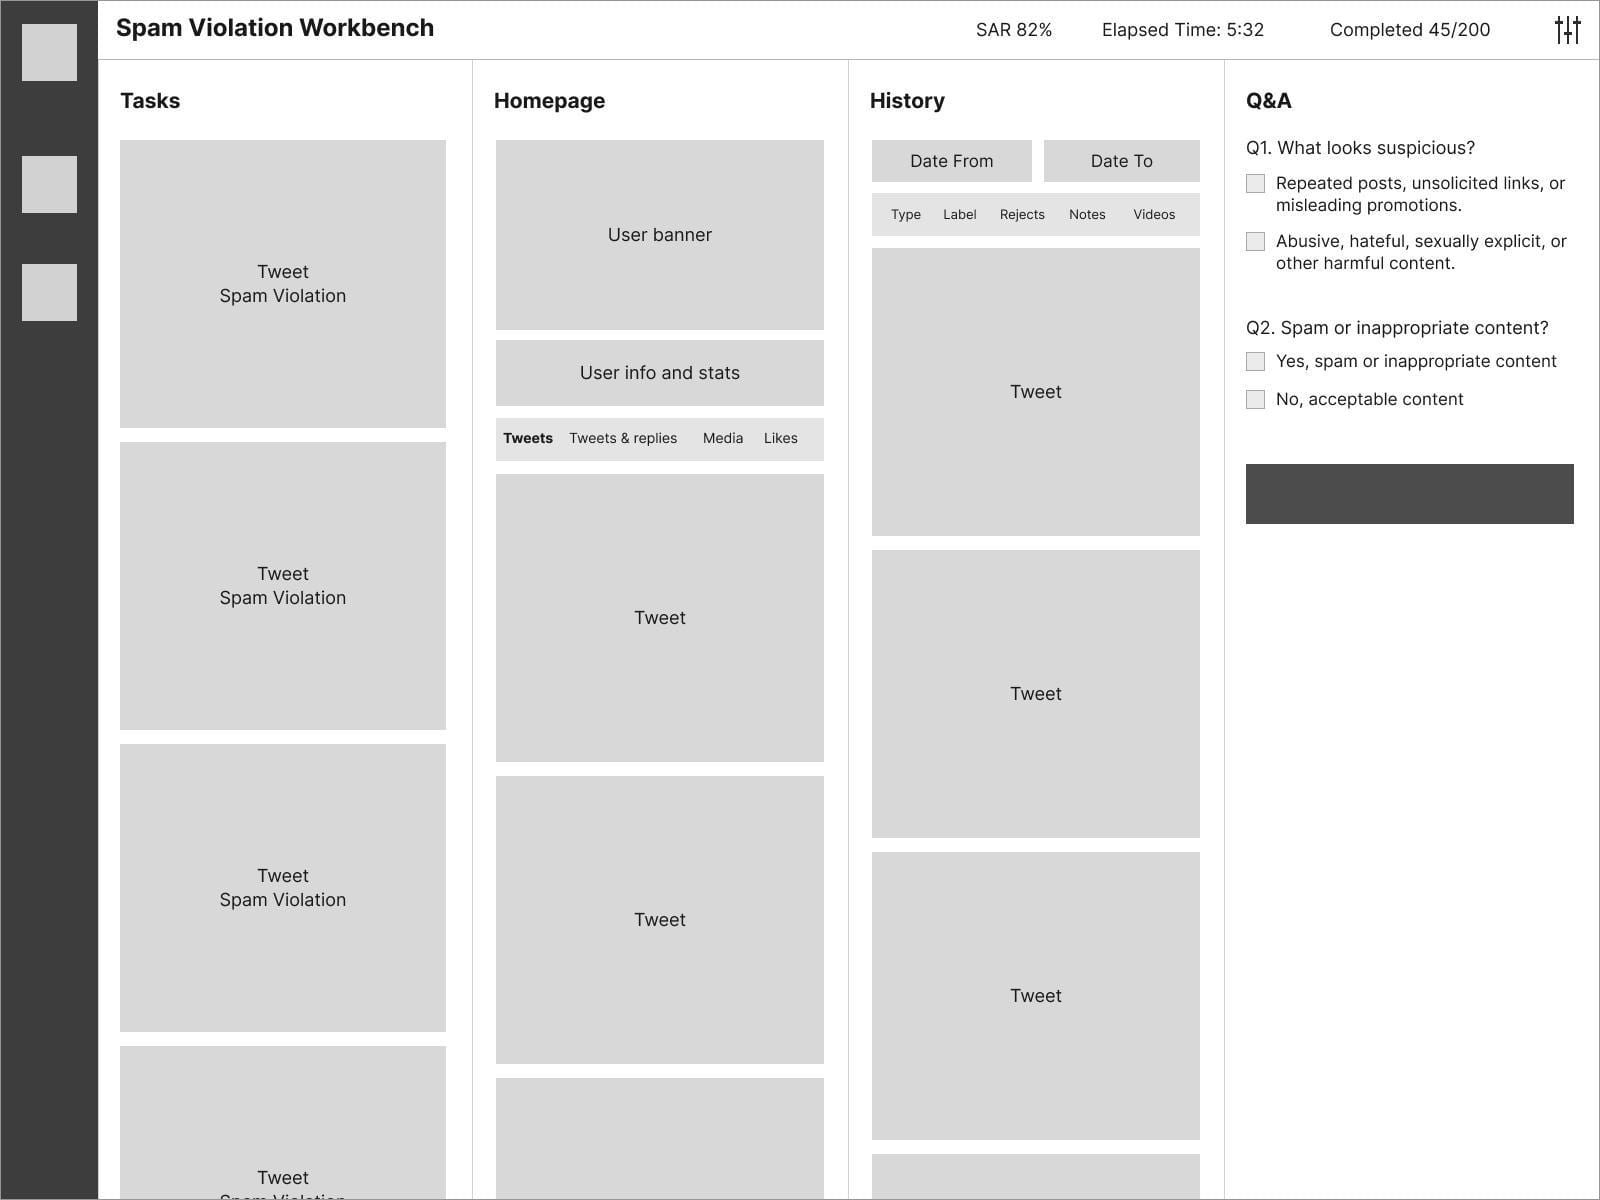
- The opportunity
- Moderators sometimes needed older tweets to investigate an account.
- My design
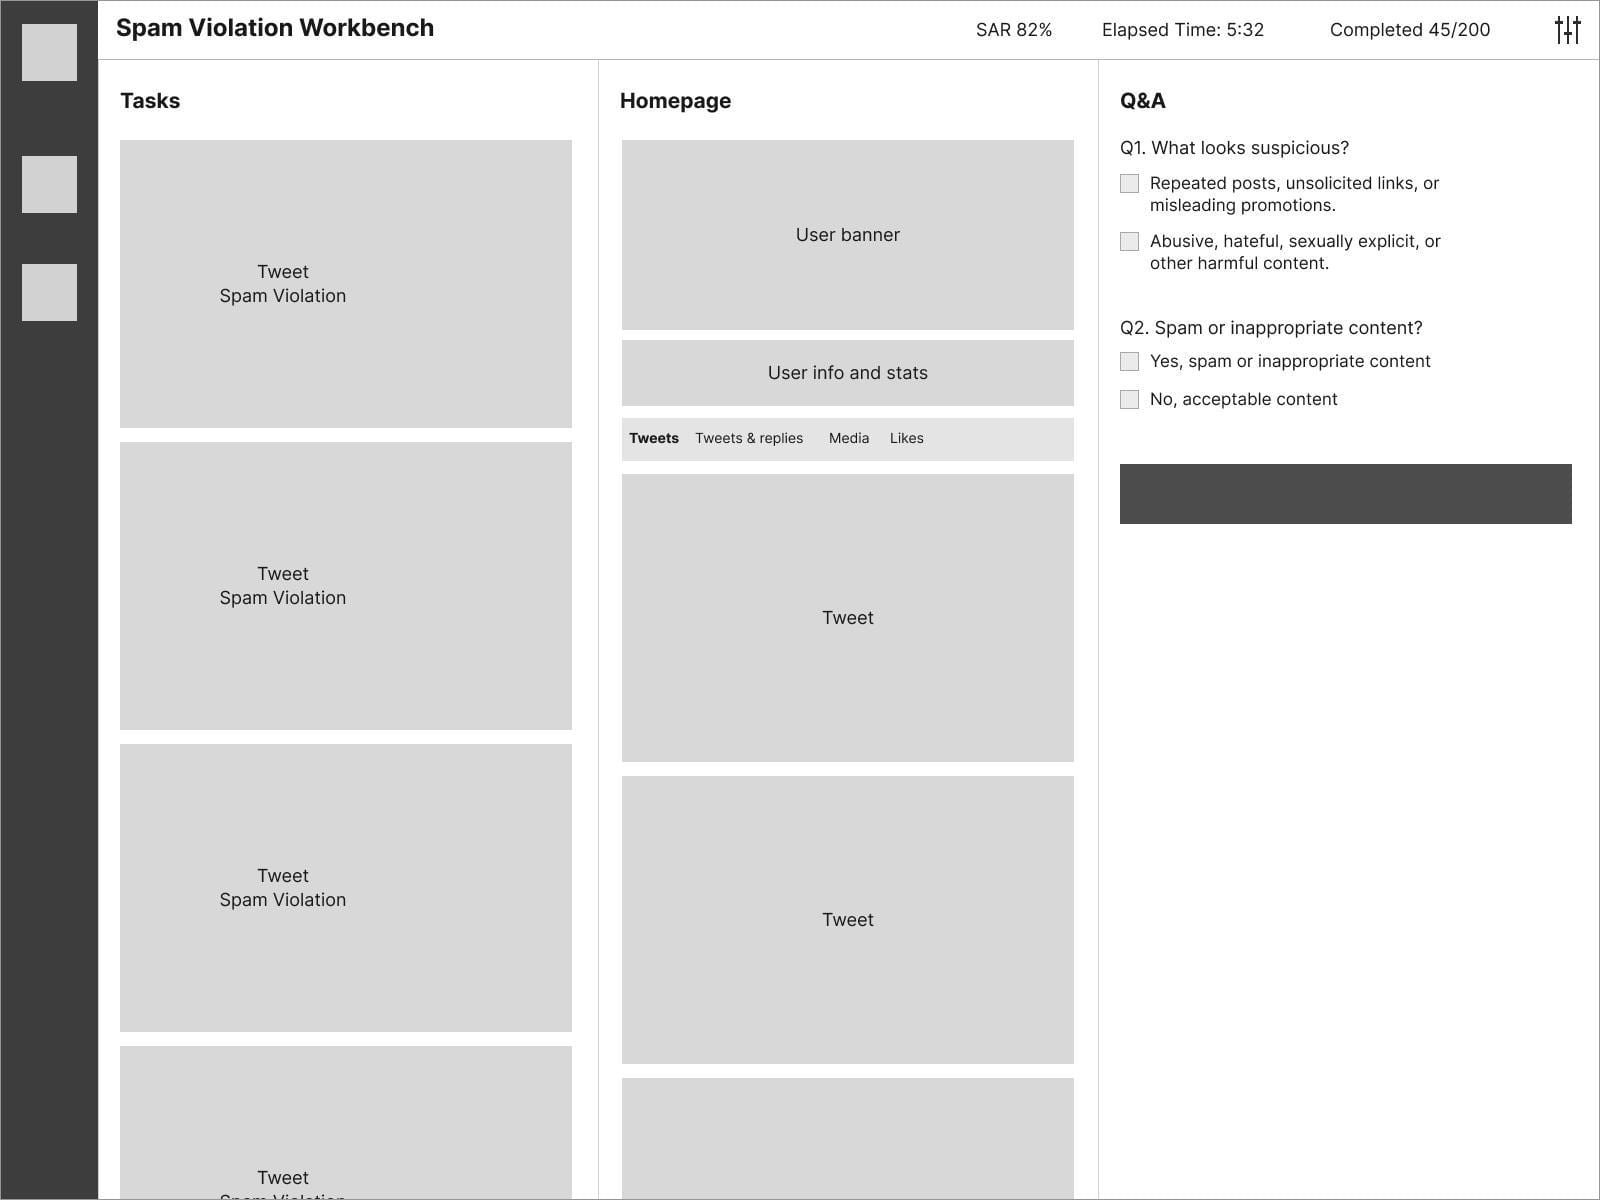
- I added a History pane with tweet search and content filters.
- The assumption
- Fewer clicks to access historic tweets would make investigations easier.
I removed complexity moderators didn’t need
- The feedback
- Four panes felt too busy. Recent Tweets and Replies were usually enough.
- My decision
- I removed the History pane and reused the existing Tweets and Replies functionality.
- The outcome
- Moderators preferred the simpler layout. I avoided building search and filtering tools that added little value to their workflow.
I started with a compact performance snapshot
- The requirement
- SAR score was Twitter’s primary KPI for annotation quality.
- My design
- I put the SAR score, elapsed time, completed tasks, and last saved in the header.
- The assumption
- A single status summary would help moderators understand their performance and progress.
I made progress visible where work happens
- The opportunity
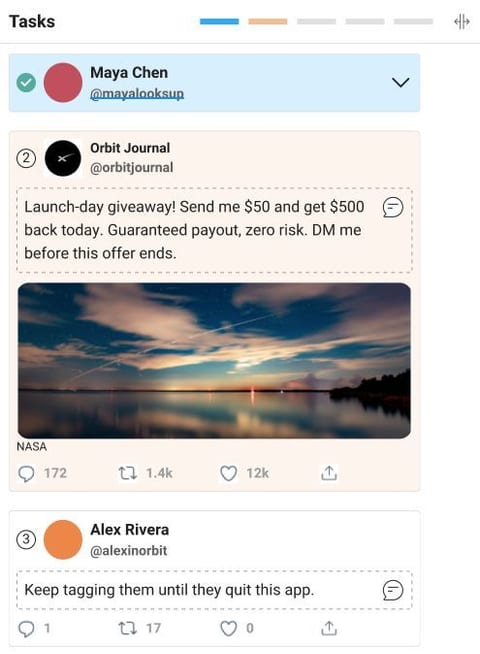
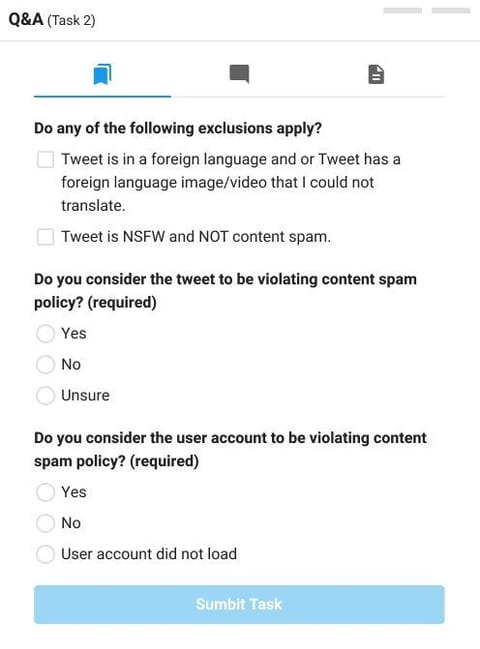
- Header totals didn’t show progress through long task and question sets.
- My decision
- I added visual progress indicators to the Tasks and Q&A panes.
- The outcome
- Stakeholders approved the change, giving moderators clearer visibility into task and question progress.
I brought translation into the investigation workflow
- The problem
- Moderators occasionally needed translation to understand ambiguous or unfamiliar content.
- My decision
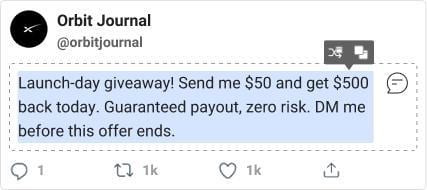
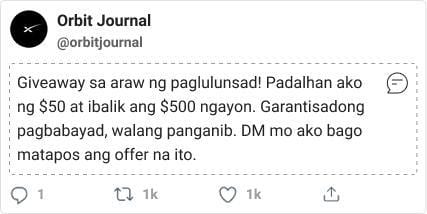
- I introduced a contextual Translate and Copy helper, available when users selected text.
- Why it mattered
- Moderators could understand difficult content without leaving their investigation or choosing a language.
Investigate, understand, and classify in one workbench
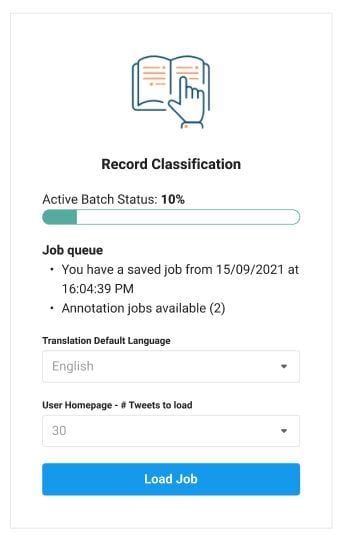
Load a job before starting the investigation
- Job queue
- See available annotation jobs and resume saved work.
- Preferences
- Use the saved translation language and select how many tweets to load.
- Load job
- Enter the workbench with the job and preferences ready.
- 1
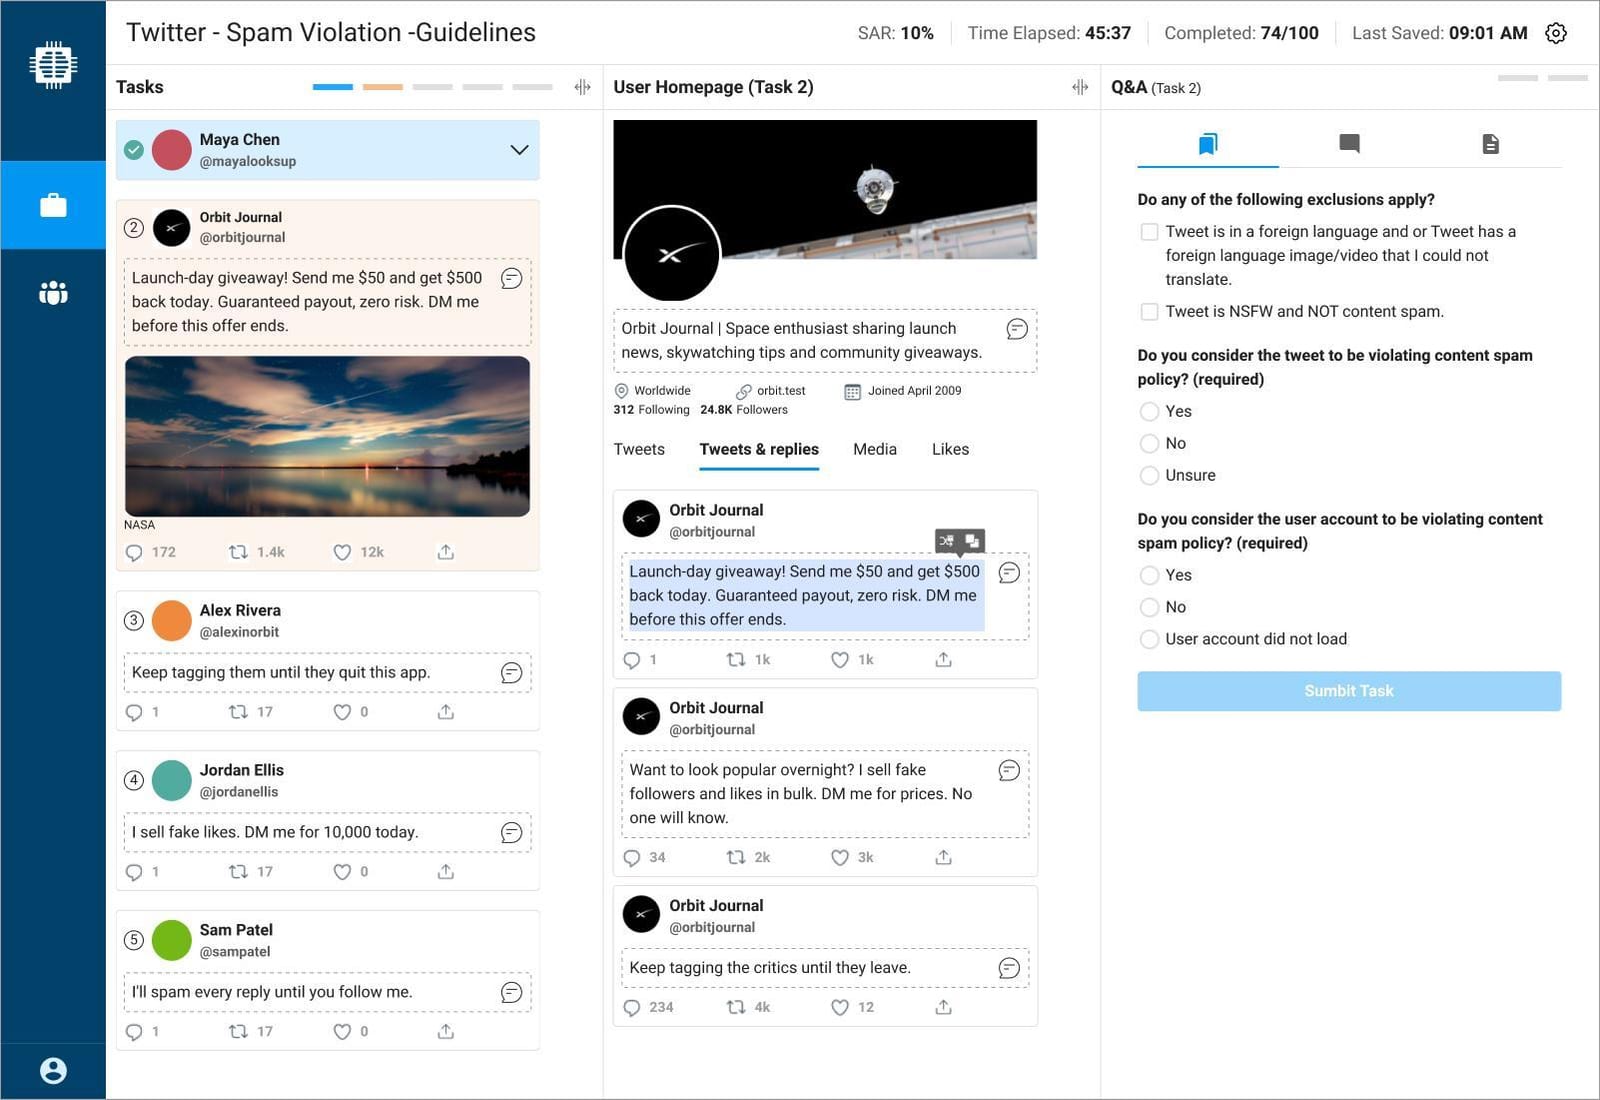
Investigate
Review the account and recent Tweets and Replies.
- 2
Understand
Translate selected text inline when needed.
- 3
Classify
Answer violation questions, track progress, and submit.
The workbench supported moderators and managers
Moderators used the workbench to investigate and classify tweets. Managers used reports to track accuracy and productivity.
Investigate and classify
Load jobs, review Twitter context, translate when needed, and complete violation questions.
Quality and throughput
Reports covered SAR, throughput, completed jobs, and time spent, helping managers see performance patterns.
Twitter targeted a 10% improvement in accuracy. The reported result was 22%.
Reported SAR improvement after three months in production, against a 10% target.
Twitter reported more consistent annotations used to support spam detection models.
Managers could track SAR and operational metrics to identify top and bottom performers.
The workbench improved. Moderator wellbeing remained a challenge.
Watch people work
Screen recordings exposed friction that interviews alone might have missed.
Challenge my own assumptions
My initial four-pane design seemed more convenient, but feedback showed that a simpler three-pane layout better supported how moderators actually worked.
Protect moderators
I’d explore ways to limit exposure to disturbing content without compromising annotation accuracy.